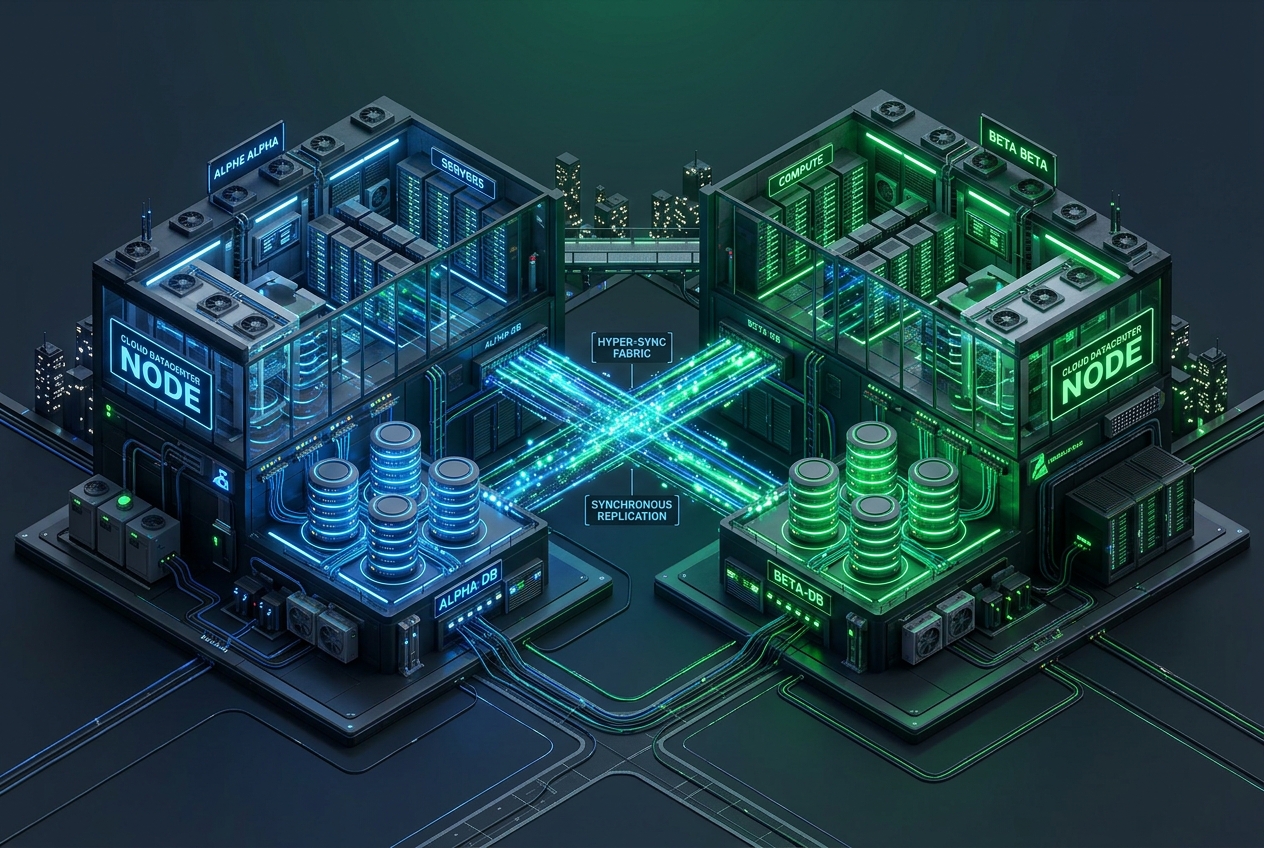
- •RPO = 0 (Zero Data Loss): Synchronous replication guarantees transaction durability across isolated server nodes.
- •RTO < 3 Seconds: Automated Patroni consensus promotes a standby node within 3 seconds of a primary node crash.
- •Seamless Maintenance: Perform zero-downtime PostgreSQL kernel updates and OS patches through rolling leader switchovers.
Why Database High Availability is Essential
Unplanned downtime costs modern software businesses thousands of dollars every minute. Implementing distributed replication allows your database tier to survive hardware failures, kernel updates, and datacenter maintenance without dropping a single active application transaction.
Synchronous vs. Asynchronous Replication
Before implementing replication, determine your latency tolerance and acceptable data loss parameters:
- Asynchronous Replication: The primary commits transactions immediately and streams WAL records in the background. Highly performant with minimal write latency penalty, but carries an RPO of milliseconds to seconds in disaster scenarios.
- Synchronous Replication: Transactions are only acknowledged after at least one standby node confirms receipt and flush to disk. Delivers strict RPO=0 at the expense of slight commit latency over the network.
Configuring PostgreSQL Primary Node
On your primary Clouds Panel database server, adjust postgresql.conf to enable write-ahead log replication:
# Replication Settings
wal_level = replica
max_wal_senders = 10
max_replication_slots = 10
wal_keep_size = 4096MB
hot_standby = on
synchronous_commit = on
synchronous_standby_names = 'FIRST 1 (node_replica_01, node_replica_02)'
Next, permit secure replication connections in pg_hba.conf over your private VPC network interface:
# Allow replication connections from standby private IP
host replication replicator 10.100.0.12/32 scram-sha-256
Automated Failover with Patroni & etcd
Manual promotion of a standby node leads to unacceptable human delays. In production, we configure Patroni with an etcd distributed consensus cluster. If the primary node fails health checks for more than 10 seconds, the etcd cluster initiates a leader election and automatically promotes the most up-to-date standby node.
Production Pro Tip
Always deploy connection poolers such as PgBouncer or HAProxy with health-check endpoints pointing to Patroni REST APIs. This ensures application servers instantly route write queries to the newly elected primary without requiring application restarts.